Most enterprise technology decisions can be revisited. Deployment model choices rarely can. When your organisation commits to a data quality platform, that decision shapes implementation timelines, dictates how much IT resource you will consume for years to come, and determines whether business teams can govern data independently or remain dependent on technical intermediaries.
Yet most enterprise buyers approach this choice without a structured framework, defaulting to procurement habits or vendor pressure rather than evidence-based criteria.
This guide changes that. Drawing on concrete decision criteria rather than vendor positioning, it gives enterprise buyers a rigorous basis for comparing cloud-native and on-premise deployment across the dimensions that matter most: time-to-value, operational burden, three-year total cost of ownership, compliance and data residency requirements, and business-user adoption. You will also find a practical decision matrix, sector-specific considerations for manufacturing and data-intensive industries, and the questions you should be asking vendors before any commitment is made.
The analysis is deployment-agnostic in its methodology. The evidence, however, tells a consistent story. Read on to understand why.
Why the Deployment Decision Is More Consequential Than Most Buyers Expect
Most enterprise software evaluations stall on feature checklists and licensing negotiations. Both matter, but neither determines whether a data quality programme actually delivers. The deployment model does. It shapes implementation speed, the IT resources consumed from day one through year three, whether business users ever meaningfully adopt the platform, and what the total cost of ownership looks like when the first contract renewal arrives.
Two data quality platforms with identical feature sets can produce fundamentally different outcomes for the same organization. The variable is not capability; it is context. Team structure, IT capacity, and data governance maturity all interact with how software is delivered. An on-premise deployment that works well in an organization with deep IT bench strength and centralized governance can quietly fail in one where business stakeholders need to own quality rules themselves.
That shift in ownership is not incidental. The move toward business-led data governance means deployment model is now a governance strategy decision, not an infrastructure footnote. Who configures quality rules, who resolves flagged issues, and who holds accountability for data accuracy on a given domain all depend on how the software is delivered and who can realistically operate it. Keep the architecture lightweight enough to use is not just a design preference; for organizations building distributed governance, it is a prerequisite.
The stakes are rising. Enterprise buyers evaluating data quality management tools in 2025 and 2026 are doing so against a backdrop of accelerating AI adoption. AI initiatives require clean, consistent, validated data before they can produce reliable outputs. Every month of implementation delay is a month of blocked AI readiness, and the cost of that delay compounds quickly.
This guide structures the decision across five criteria: implementation timeline, IT burden, total cost of ownership, compliance and data residency, and governance model fit. Each criterion systematically favors one deployment model depending on your organizational context, and the analysis that follows treats each one honestly.
Defining the Models: What Cloud-Native and On-Premise Actually Mean in 2026
Before evaluating any data quality platform on features or price, you need to confirm what deployment model it actually uses, because the label vendors apply and the architecture underneath it are not always the same thing.
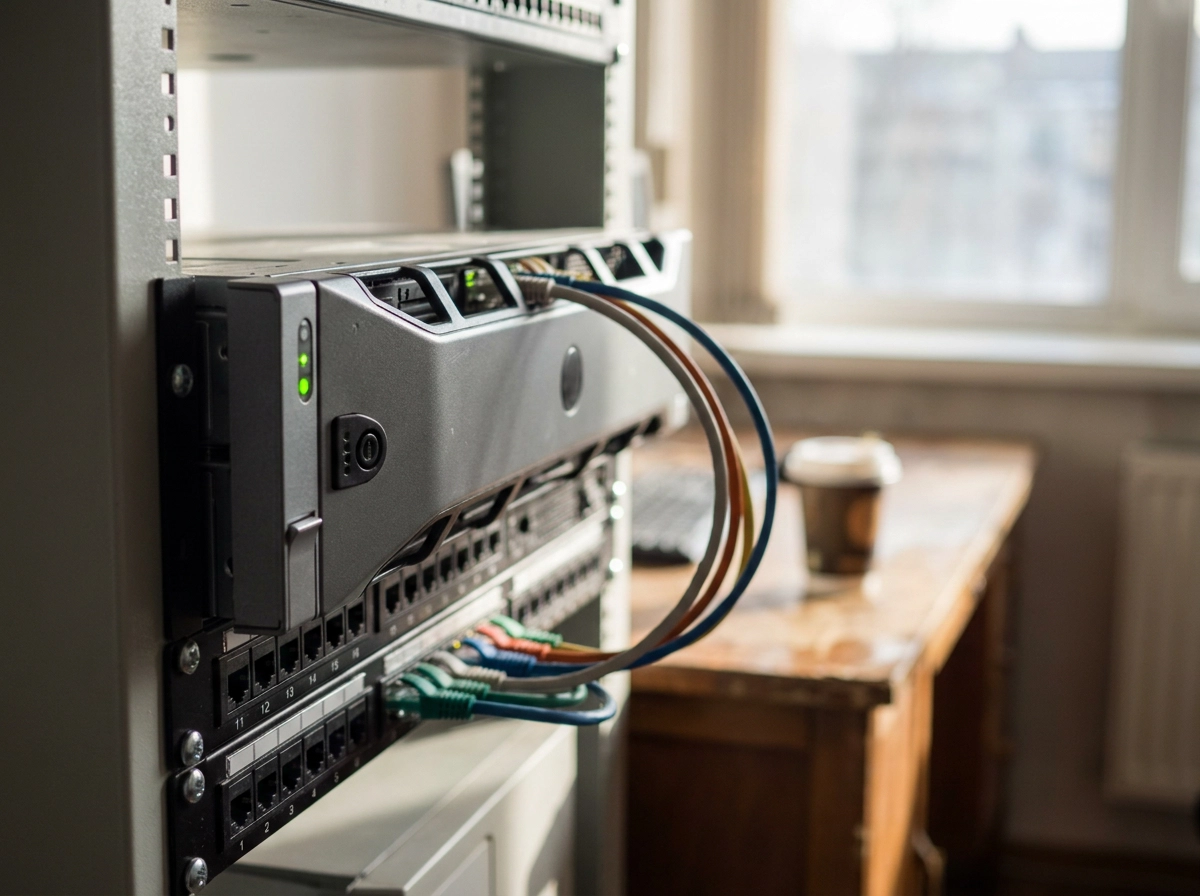
On-premise means the software runs on infrastructure your enterprise owns and operates. Servers, storage, and networking are internal responsibilities. Every upgrade, security patch, and scaling event requires IT involvement. Your team controls the environment entirely, and carries the full operational burden that comes with it.
Cloud-native is a distinct architectural category, not simply software that runs on someone else’s servers. True cloud-native data quality tools are built from the ground up for cloud delivery, using multi-tenant SaaS architecture, API-first design, and continuous deployment pipelines. This changes the customer experience fundamentally: the vendor manages infrastructure, releases, and platform availability, while your team focuses on configuration and governance.
A third model sits between these two: hosted or private-cloud deployment, where vendor software runs on cloud infrastructure under a dedicated single-tenant instance. This preserves some cloud benefits, particularly reduced hardware ownership, but retains dedicated-instance maintenance patterns and cost structures closer to on-premise than to true SaaS.
The practical gap between cloud-native and on-premise shows up fastest at onboarding. Cloud-native platforms connect to data sources via APIs or pre-built connectors, while on-premise installations require infrastructure provisioning, security review, and environment configuration before any meaningful setup begins, adding material time to the critical path before a business user sees anything.
One distinction enterprise buyers frequently miss: some vendors market products as “cloud” that are architecturally on-premise deployments hosted remotely. The architecture determines the maintenance burden, not the hosting location. A remotely hosted legacy tool preserves upgrade cycles, dedicated-instance costs, and IT dependency, without delivering the agility of a genuinely cloud-native platform. Confirm the architecture before shortlisting.
Criterion 1: Implementation Timeline and Time-to-Value
The architectural differences outlined above have immediate practical consequences when implementation begins.
On-premise data quality implementations in enterprise environments typically run many months from procurement to production. Hardware acquisition, environment configuration, security review, and staged rollout stack sequentially, and none of those phases can begin until the previous one closes. Business users see no value during that window.
Cloud-native data quality platforms remove infrastructure provisioning from the critical path entirely, and organizations with clear data source documentation and a designated business owner can reach a working proof-of-concept significantly faster than on-premise alternatives, a shift that is established at go-live and holds throughout the contract term.
Implementation delay is not a scheduling inconvenience. It is a business risk. During the months an on-premise deployment is still in progress, operational decisions continue to run on unreliable data. More critically, AI initiatives that depend on clean, structured data inputs are blocked until the platform is live and validated. For enterprises under competitive pressure to operationalize AI, a slow deployment model directly delays that capability.
Criterion 2: IT Resource Requirements and Ongoing Operational Burden
Implementation timeline is only half the operational story. The other half compounds quietly after go-live, and it consistently catches enterprise buyers off guard.
On-premise data quality software assigns a permanent operational workload to IT: infrastructure availability, backup and recovery, security patching, version upgrades, and performance tuning. This load does not shrink as the platform matures. It competes with every other IT priority on the roadmap, and in constrained departments, it loses ground regularly.
The cost that most licensing comparisons miss is internal IT headcount. In large enterprises, a platform administrator role is rarely created explicitly for a data quality deployment. Instead, the work is absorbed across DBAs, infrastructure engineers, and IT operations staff, each carrying a partial allocation. These fractions rarely appear in procurement models but surface reliably in three-year retrospective reviews, often representing more cost than the original licence fee.
Cloud-native data quality platforms transfer infrastructure responsibility to the vendor. IT’s role shifts from platform administration to integration architecture and security governance, which are higher-value activities that align with how modern IT teams want to operate, a shift from operator to overseer that is established at go-live and holds throughout the contract term.
This shift also enables what data governance software needs to do at an organisational level: putting control in the hands of data stewards, domain owners, and analysts. Role-based access, no-code rule builders, and browser-based interfaces are native to SaaS design. On-premise tools rarely offer these patterns without custom development, which reintroduces IT dependency through the back door.
The practical evaluation discipline here is temporal modelling. When assessing data quality tools, map expected IT involvement at months six, twelve, and twenty-four post-launch for each deployment option. The initial integration effort is only the entry cost; the ongoing footprint determines the true operational burden over a three-year horizon.
Criterion 3: Three-Year Total Cost of Ownership Framework
The operational burden difference between models is one input into total cost. The fuller picture requires modelling all five cost categories across a three-year horizon before drawing any conclusion.
Those five categories apply to both deployment models: software licensing or subscription fees, infrastructure costs, implementation and professional services, ongoing IT operational costs, and upgrade or migration costs. A TCO comparison that omits any one of them will misrepresent the decision.
On-premise TCO profile. Year 1 carries the heaviest load: a perpetual licence fee, significant infrastructure spend unless hardware already exists, and substantial professional services to reach production. Years 2 and 3 bring moderate but persistent IT operational costs alongside annual maintenance fees that typically represent a significant recurring percentage of the original licence value. Every two to four years, a major version upgrade triggers what amounts to a mini-implementation, adding unplanned professional services spend that rarely appears in the original business case.
Cloud-native TCO profile. Subscription fees scale with usage or user count, infrastructure costs are effectively zero, and professional services spend is compressed because onboarding is faster. IT operational overhead stays minimal throughout the contract term. Critically, continuous feature delivery replaces discrete upgrade projects, eliminating the periodic cost spikes that inflate on-premise three-year totals.
The crossover point. On-premise can appear cheaper in Year 1 when existing hardware absorbs infrastructure costs. Cloud-native accumulates its structural advantage progressively through avoided maintenance, eliminated upgrade cycles, and lower IT labour. For most enterprise deployments, the comparison shifts decisively by Year 3.
Build your TCO model with these line items: hardware or cloud infrastructure, internal IT hours at fully loaded cost, vendor licence and support fees, implementation partner fees, training, and estimated productivity value from faster time-to-value. Internal IT hours at loaded cost is the line item most commonly omitted and most consequential when included.
Illustrative Three-Year TCO Comparison: Cloud-Native vs. On-Premise
The framework above defines what to model. The table below shows what those inputs look like when populated for a representative mid-size enterprise deployment. The hour ranges and cost percentages below are illustrative order-of-magnitude estimates, not empirically benchmarked figures; replace them with vendor-confirmed data during your own evaluation.
| Cost Category | Year 1: On-Premise | Year 1: Cloud-Native |
|---|---|---|
| Software fee | Perpetual licence (large upfront) | Annual subscription |
| Infrastructure | Server, storage procurement | None |
| IT configuration | Substantial DBA and IT hours | Reduced IT hours (API/connector setup) |
| Implementation services | Implementation partner engagement | Vendor-led onboarding + limited rule configuration support |
| Business disruption | Downtime during cutover | Minimal |
| Cost Category | Years 2–3: On-Premise | Years 2–3: Cloud-Native |
|---|---|---|
| Software fee | Annual maintenance: significant recurring percentage of licence value | Subscription renewal, volume-based scaling |
| Infrastructure | Patch management, performance tuning as data volumes grow | Near-zero |
| IT operational hours | Ongoing monthly IT hours | Near-zero |
| Feature updates | Discrete upgrade projects, additional services spend | Included in subscription |
The pattern that emerges is structural, not marginal. As the framework above establishes, on-premise costs recur and compound; cloud-native costs stay infrastructure-flat.
When internal IT labour is costed at loaded rates rather than treated as sunk overhead, the hidden operational cost of on-premise deployments can materially shift the three-year comparison in favour of cloud-native, particularly in enterprises where IT capacity is constrained.
Criterion 4: Compliance, Data Residency, and Security Considerations
Cost comparisons tell part of the story. Compliance concerns often determine which deployment model enterprise buyers consider viable in the first place.
Data residency is the most commonly cited reason for defaulting to on-premise, and in some cases it reflects a genuine constraint. Organizations subject to GDPR, sector-specific localization rules in financial services or healthcare, or internal data classification policies may face real restrictions on where data quality processing can occur. These constraints deserve rigorous scrutiny, not reflexive acceptance.
Cloud-native data quality platforms have responded to this objection directly. Leading platforms now offer regional data residency configurations, EU-only processing guarantees, and dedicated private deployment options. For most regulated enterprises, these configurations resolve the compliance concern without reverting to full on-premise infrastructure and its associated operational burden.
The security comparison has also shifted materially. Leading cloud-native platforms deployed on enterprise-grade infrastructure frequently carry certifications such as ISO 27001 and SOC 2 Type II, verify specific certifications with each vendor during evaluation. A well-configured cloud deployment with current certifications can present a security posture comparable to, or stronger than, on-premise environments where patching cycles lag, though this must be verified case by case.
Audit trail and lineage requirements, which sit at the center of any evaluation of enterprise data quality software, favor cloud-native deployments. Activity logging is centralized by default and surfaced through built-in dashboards. On-premise equivalents require separate configuration, dedicated storage allocation, and ongoing maintenance to produce the same audit record.
The takeaway for enterprise buyers: compliance is not an automatic argument for on-premise. The correct process is to document your specific regulatory requirements, map them to what each deployment model can structurally support, and challenge vendors directly on their compliance architecture before letting assumption drive the decision.
Criterion 5: Data Governance Model Fit and Business-User Adoption
Compliance requirements narrow the deployment decision for some buyers. Governance model fit determines whether the platform actually gets used once it’s deployed.
This criterion is the most underweighted in enterprise deployment comparisons. IT-owned, centralized governance, the on-premise/centralized IT model described in Criterion 5, aligns naturally with on-premise infrastructure, but that model works only until the organization decides that data stewards, domain owners, and business analysts, not IT, should own data quality day-to-day. At that point, the deployment model becomes a governance strategy constraint.
Cloud-native data governance software teams actually use is built with business users as the primary actor, not a secondary one. Web-based interfaces, no-code rule configuration, role-based access, and notification-driven workflows let a supply chain manager flag a threshold issue or a data steward add a validation rule without opening an IT ticket or waiting for DBA availability. The governance loop closes in hours, not sprint cycles.
On-premise data quality tools typically require SQL-level access or IT intermediation for rule changes, new data source connections, and threshold adjustments. Each of those dependencies creates a bottleneck. When a data quality issue surfaces in an operational dataset, the organization’s ability to respond is gated by IT queue depth, not business urgency.
Adoption rate is the metric that most honestly predicts platform value. A technically sophisticated on-premise deployment with low business-user engagement delivers less measurable improvement than a simpler cloud-native tool used actively across the organization every day. The 2025 DATAVERSITY Trends in Data Management Survey found 61% of respondents identify data quality as a top challenge, suggesting execution gaps persist regardless of tooling investment.
For enterprises building AI capabilities, this criterion compounds. Data owners who actively maintain quality rules and resolve flagged issues in near-real time produce cleaner, more consistent data pipelines. Organizations where data quality remains a periodic IT project hand AI initiatives inconsistent inputs, and the downstream cost shows up in model reliability, not just dashboards.
The Decision Matrix: Which Deployment Model Fits Your Organisation
Governance model fit is the most predictive single criterion, but no one criterion should drive the decision alone. Apply all five in combination.
Cloud-native is the stronger default for organizations where any of the following are true: IT capacity is constrained and cannot absorb ongoing platform operations; business stakeholders need to own data quality processes without IT intermediation; AI or advanced analytics programs require data readiness faster than on-premise implementation cycles allow; operations span multiple geographies where centralised infrastructure creates access latency; or a legacy on-premise tool has already failed to achieve adoption. Each condition independently tips the scoring toward cloud-native. In combination, they make the case decisive.
On-premise remains defensible in four specific circumstances: hard regulatory or contractual data residency requirements that no cloud vendor’s architecture can satisfy; existing infrastructure with significant remaining useful life that resets the TCO comparison; air-gapped environments (defense, critical national infrastructure) where cloud connectivity is operationally prohibited; or large, capable IT teams with platform-specific expertise and genuine capacity to absorb the operational load. Outside these conditions, on-premise is a legacy default, not a strategic choice.
To score your own context, rate each of the five criteria covered in this guide (implementation timeline, IT burden, TCO, compliance fit, governance model) on a 1-to-5 scale for both deployment options, then weight each criterion by its strategic priority for your organization. The weighted totals produce a deployment recommendation grounded in your actual constraints rather than vendor positioning. This is especially useful when connecting legacy systems without waiting for a replacement program is a near-term business requirement.
On hybrid deployments: cloud processing over on-premise storage, or a cloud governance layer above an on-premise data warehouse, adds architectural complexity that increases both implementation time and operational cost. Choose hybrid only when specific requirements genuinely cannot be met by either pure model.
The same platform evaluated against two organizations with different IT capacity and governance ambitions can produce opposite deployment recommendations. Criteria-based scoring surfaces that reality. Vendor-led demos do not.
Sector-Specific Considerations: Manufacturing and Data-Heavy Industries
The criteria-based framework above applies universally, but manufacturing enterprises carry specific pressures that make deployment model selection more consequential than in most other sectors.
In manufacturing, data quality failures are not abstract. Errors in product master data, supplier records, or bill-of-materials entries propagate directly into production runs, procurement orders, and warranty claims. The operational cost of those errors starts accumulating the moment a data quality program is delayed, which means time-to-value on a data quality platform is not a convenience metric but a direct input to financial performance.
The architecture of manufacturing operations compounds this. A global manufacturer operating ten plants across five countries, each with its own ERP instance and supplier network, faces a structurally difficult problem if it tries to centralise data quality enforcement on-premise. Cloud-native platforms that connect to distributed data sources via API are built for exactly this topology. On-premise deployments that assume a single, controlled data environment require significant custom integration work before they can even address the multi-site reality.
Regulatory compliance adds a third pressure point. In manufacturing, common compliance obligations, including product traceability, quality audit standards, and substance documentation requirements, all depend on reliable data lineage. Cloud-native data governance software with centralised, immutable activity logging satisfies these requirements structurally. On-premise configurations typically require custom audit infrastructure built on top of the platform, which introduces both cost and fragility.
Finally, supply chain AI use cases, demand forecasting, production optimisation, predictive maintenance, depend on validated, consistent data inputs. As Criterion 1 establishes, every month of implementation delay is a month error rates continue unaddressed, a cost that is direct and operational in manufacturing, not abstract.
TikeanDQ was designed with precisely this industrial context in mind. Its lightweight, business-oriented architecture lets operational teams and data stewards configure domain-specific quality rules directly, without routing every change through a data engineering backlog.
What to Ask Vendors Before You Commit to a Deployment Model
Regardless of which deployment model you favour after applying the criteria above, vendor answers to these questions separate credible platforms from well-marketed ones.
For cloud-native vendors, ask:
- Where is data processed and stored, and what regional residency options are available?
- Which certifications cover the platform: ISO 27001, SOC 2 Type II, or both?
- What is the contractual uptime SLA, and what compensation applies when it is breached?
For on-premise vendors, ask:
- What IT resource hours are required for initial deployment and for ongoing operations at months six and twelve?
- How does the version upgrade process work, how frequently are major releases issued, and what do they cost?
- What professional services are required, and what is the typical engagement fee?
For both models, demand:
- A concrete walkthrough of how a business user, not an IT administrator, configures and modifies a data quality rule
- A week-by-week onboarding plan covering weeks one through four
- Reference customers of comparable size and industry who went live within the last twelve months, with direct contact available
On TCO, require a written model that includes:
- All infrastructure, licensing, implementation, and support costs across three years
- The specific cost variables that change as data volumes increase or user counts grow
- The price of adding a single new data source connection, which frequently exposes hidden scaling costs
On governance, push vendors to demonstrate:
- How data quality issues are surfaced and assigned to business owners, not queued for IT
- What workflow and notification capabilities exist for issue resolution and escalation
- How the platform supports domain owners managing quality for their own data without IT involvement, which is the defining characteristic of a mature data stewardship model
Vendors who struggle with these questions under structured evaluation rarely perform better in production.
Making the Decision: Key Takeaways for Enterprise Buyers
With your vendor questions answered, the framework in this guide reduces to five conclusions enterprise buyers should carry into the final decision.
Cloud-native is the stronger default in 2025. For most large enterprises, cloud-native data quality platforms deliver faster time-to-value, lower three-year TCO, and better structural conditions for business-led data governance than legacy on-premise alternatives. That case rests on evidence across implementation timelines, IT operational burden, and adoption rates, not on vendor positioning. Apply the scoring criteria in this guide to your specific organisational context before committing.
On-premise remains justified only in the narrowing set of cases identified in the Decision Matrix: hard residency constraints, air-gapped environments, and infrastructure with significant remaining useful life.
Sequence your evaluation correctly. Start with IT burden and governance model fit before you open a pricing conversation. These two criteria most reliably predict whether a deployment delivers sustained adoption or becomes an underused infrastructure investment. A platform that business users cannot operate independently will underperform regardless of its feature depth.
Build an honest TCO model. Use the three-year framework in this guide and include internal IT labour at loaded cost, not just licensing fees. That single adjustment routinely shifts the comparison materially. Bring that model to procurement or the board, not a vendor-supplied cost estimate.
Include TikeanDQ on your shortlist. If you are evaluating lightweight, business-oriented cloud-native data quality management tools for a large enterprise or global operation, TikeanDQ is built for exactly this deployment context. Its architecture prioritises business-stakeholder access and rapid deployment, which maps directly to the criteria this guide identifies as most consequential.